GuidesUpdated

MiniMax H3 Prompting Guide T2VA to Ref2VA Prompt Examples

A MiniMax H3 Max prompt guide: pick the mode from your files, fill each field, paste.

This MiniMax H3 prompting guide starts from the files you have. No still is T2VA, one opening still is I2VA, one ending still is L2VA, and an opening plus an ending still is FL2VA. Those four take an alignment line and three fields in a fixed order. Extra images, clips or audio as references go to Ref2VA, which uses six sections instead. Each mode comes with a copy-ready MiniMax H3 prompt to paste into the MiniMax H3 Max video generator.

  • T2VA, I2VA, FL2VA, L2VA and Ref2VA
  • Copy-ready MiniMax H3 prompt examples
  • Three fields; six sections for Ref2VA
  • Built on MiniMax's public prompt guide

TLDR

1. Count your stills before you write. No image is T2VA. One opening still is I2VA. One ending still is L2VA. Opening plus ending is FL2VA (MiniMax video prompt-writing guide).

2. Write three fields in this order: integrated_multimodal_description, overall_soundscape, non_diegetic_music (same guide; GitHub copy).

3. Keyframe modes need a first-line alignment instruction, then a blank line, then the three fields. T2VA skips that line.

4. MiniMax H3 Max returns a short clip with native stereo, up to 15 seconds, at up to 2K (MiniMax H3 launch post; open-source specs).

5. Paste the finished block into the MiniMax H3 Max video generator and attach the stills the mode expects.

MiniMax video prompt-writing guide (Hugging Face)

Key Takeaways

  • Mode is an asset decision, not a vibe decision.

    The stills you actually have pick T2VA / I2VA / FL2VA / L2VA; picking the wrong one locks the picture to the wrong moment on the timeline (prompt-writing guide).

  • The three fields do different jobs.

    Picture, action, cuts, speakers, and spoken lines live in integrated_multimodal_description. Room tone, footsteps, and non-verbal human sound live in overall_soundscape. Score the characters cannot hear lives in non_diegetic_music.

  • Shot 1 has no clock.

    Later shots start with a rising cut time inside the clip length. A timestamp on Shot 1 is a documented miss (guide §4.2).

  • Camera is a sentence, not a tag pile.

    Write motion type + amplitude + speed inside the shot: “The camera pushes in with small amplitude at slow speed…” (guide §4.3).

  • Duration is a number you must keep honest.

    Public output is 4–15 seconds as whole seconds; S.SS on a last-frame line has to match the length you generate (platform video guide; prompt-writing skill).

  • Try path:

    Paste Prompt 1 or Prompt 2 into the video generator. Need a still first? Build it on the image page, then come back to video.

Pick the mode from the stills you have

MiniMax’s public prompt-writing guide splits four text/keyframe shapes (Hugging Face guide; GitHub base-en.txt). The platform docs describe the same family as text-to-video, first/last-frame image-to-video, and a separate full-reference path (video generation guide; GitHub README). Ref2VA is another format: six sections, not the three-field keyframe body. The Ref2VA section further down covers it.

Only a sentenceT2VABuild the whole timeline in the three fields. No alignment line.An I2VA/FL2VA/L2VA first line asks for a Picture 1 you never attached, so the opening (or ending) has nothing to lock.
One still that should be the first frameI2VAFirst line pins Picture 1 to 0.00s / Shot 1, then the body walks forward.Writing it as L2VA treats that still as the ending. The clip will try to arrive there instead of starting there.
One still that should be the last frameL2VAFirst line pins Picture 1 to S.SS / the final shot, then the body converges.Writing it as I2VA freezes the still at 0.00s. The ending is unconstrained, so you often lose the pose you cared about.
Two stills: start and endFL2VAFirst line maps Picture 1 to 0.00s and Picture 2 to S.SS. Prefer one shot so the path can actually land.Extra cuts in the body can finish on a shot that is not the last-frame picture. T2VA with two uploads ignores the alignment contract.
Many images, clips, or audio as reusable referencesRef2VA (six sections, below)Full-reference is a six-section format, not these three fields.Stuffing extra assets into a keyframe prompt drops identities, motion, or voice the three-field shape cannot name.

Alignment lines (copy the exact sentence)

T2VA — skip this. Start on integrated_multimodal_description.

MiniMax video prompt-writing guide (Hugging Face)

I2VA

Alignment line
Use this prompt

For the target video, at 0.00 seconds into the target video, <Picture 1> (from Shot 1) is fully referenced.

  1. What it does — First line pins Picture 1 to 0.00s / Shot 1, then the body walks forward.
  2. Line one — Put this instruction on line one, then one blank line, then the three fields (guide §2.1).

FL2VA

Alignment line
Use this prompt

How the reference pictures align with the target video — Picture 1 (from Shot 1) aligns with the 0.00-second mark of the target video; Picture 2 (from Shot N) aligns with the S.SS-second mark of the target video.

  1. What it does — First line maps Picture 1 to 0.00s and Picture 2 to S.SS. Prefer one shot so the path can actually land.
  2. N — N is the last shot index.
  3. S.SS — S.SS is the clip length to two decimals (8.00 if you generate 8 seconds).
  4. Line one — Put this instruction on line one, then one blank line, then the three fields (guide §2.1).

L2VA

Alignment line

How the reference pictures align with the target video — <Picture 1> (from Shot N) aligns with the S.SS-second mark of the target video.

  1. What it does — First line pins Picture 1 to S.SS / the final shot, then the body converges.
  2. N — N is the last shot index.
  3. S.SS — S.SS is the clip length to two decimals (8.00 if you generate 8 seconds).
  4. Line one — Put this instruction on line one, then one blank line, then the three fields (guide §2.1).

What belongs in each of the three fields

Field order is fixed (guide §2.2): 1. integrated_multimodal_description 2. overall_soundscape 3. non_diegetic_music

integrated_multimodal_descriptionStyle, first composition, wardrobe, props, action, cuts, camera sentences, speaker IDs such as (S1), spoken/sung lines in the d-tags shown in the copy-paste blocks, on-screen type in English double quotes, diegetic sound tied to a beat (a scanner beep as it happens, a radio the clerk can hear)Mood essays (“emotional,” “epic”). Abstract camera tags dumped at the end of the shot. Score the characters cannot hear.
overall_soundscape1–4 sentences of ambience + physical action + non-verbal human sound for the whole clip (rain, fans, footsteps, paper, a breath, a laugh)Dialogue, lyrics, or diegetic music (those already live in the description). Do not repeat lines you already wrote. Use N/A only if you asked for complete silence.
non_diegetic_music1–3 sentences of audible score: instruments, tempo, rhythm, volume change. Characters cannot hear this.Abstract mood words (“sad,” “uplifting,” “emotional function”). Phone/TV/radio music the characters can hear belongs in the description. Use N/A when there is no score.

Common “right fact, wrong slot” mistakes

  • Spoken line in overall_soundscape.

    The mouth and the words belong in the description with (S1) and <d>. Soundscape may keep a laugh or a breath, not the sentence.

  • “Emotional piano” in non_diegetic_music.

    Name the instrument, tempo, and dynamics. Drop the mood adjective.

  • Camera as a label stack.

    Push In, Slow, Small at the end of a shot is weaker than one English sentence with type + amplitude + speed (guide §4.3).

  • On-screen type rewritten.

    A neon sign, carton mark, or UI string stays in English double quotes, original words and punctuation, no translation (guide §4.5).

  • Dialogue rewritten “to sound better.”

    Inside <d>, keep the user’s language tag and the exact spoken string. Identifying the speaker stays outside <d> (guide §4.4).

Failure boundaries (check these before you generate)

These are the misses the public guide calls out. They are a reliable way to waste a take.

Add a timestamp to Shot 1The opening clock fights the alignment line (or invents a start time T2VA does not use)Shot 1: style + composition only. First clock goes on Shot 2+, rising, inside the clip length ([Shot 2] At 00:04.500, …)
Stack camera labels instead of a sentenceMotion is ignored or snapsThe camera pushes in with small amplitude at slow speed toward the receipt.
Put dialogue in overall_soundscapeLips and words drift; the line never attaches to (S1)Move the spoken string into the description, inside <d>. Keep soundscape for room and body noise.
Score with abstract mood wordsMusic is generic or fights the pictureInstruments + tempo + volume change. Or N/A.
Translate or polish spoken lines / on-screen typeThe model “helps” and you lose the line you neededQuote the original. Language tag inside <d>. Carton marks in "double quotes".
FL2VA with several cutsPicture 2 never becomes the last frame of the last shotOne shot from Picture 1 → Picture 2, unless you truly need a cut and still land Shot N on Picture 2 at S.SS
S.SS does not match durationLast-frame lock is early, late, or missingGenerate 8 seconds → write 8.00. Platform duration is 4–15 whole seconds (platform specs)

Public output for MiniMax H3 Max

Public output story for MiniMax H3 Max: up to 15 seconds, up to 2K, native stereo, 24 fps in the open-source spec sheet (launch post; open-source announcement; Jul. 31, 2026 release notes). Hosted resolution is described as 768P / 2K (platform specs). Plan one beat per generate.

Weak prompt → structured prompt (two originals)

These are rewrites, not the four official bakery / train / cyclist / glass cases. Steal the shape. Do not paste those four scenes as your brief.

Prompt 1 — T2VA (no still)

Weak start: “cinematic convenience store, clerk talks, emotional music, 8 seconds.”

Why it fails: no shot list, no speaker ID, mood-word score, no soundscape/music split, no duration math.

Copy-paste (8-second T2VA)
Use this prompt

integrated_multimodal_description: [Shot 1] Live-action, cinematic, a medium shot frames a late-night convenience store counter as a clerk in a navy polo scans a glass bottle of barley tea. Fluorescent light reflects on the wet raincoat of the customer across the counter. The camera trucks left with small amplitude at slow speed as the clerk with a low, even voice (S1) says: <d>[English] Receipt in the bag?</d> [Shot 2] At 00:04.500, the camera cuts to a close-up of the thermal printer peeling a receipt while the clerk's last words carry over from the previous shot. overall_soundscape: Cooler fans hum behind the counter while rain ticks against the glass doors. The barcode scanner beeps once, followed by the soft tear of thermal paper. non_diegetic_music: A muted electric-piano figure at a slow tempo, joined by a low analog bass pulse that fades after the receipt prints.

What changed
Shot 1 has no clock; Shot 2 is 00:04.500 inside 8 seconds; camera is a sentence; the spoken line is inside <d> with (S1) outside; soundscape is room + action; music names instruments instead of “emotional.”

Text-to-video look reference hosted on MiniMax H3 Max · use it to plan motion, not as a graded master

Text-to-video look reference still hosted on MiniMax H3 Max

Prompt 2 — FL2VA (two product stills)

Weak start: “animate these two pack shots, zoom in, upbeat music, a few cuts.”

Why it fails: FL2VA wants a path between two frames, usually in one shot. “A few cuts” plus a mood-word score is how Picture 2 never arrives.

Attach the closed carton as Picture 1 and the opened carton + mug as Picture 2.

Need only one opening still instead of two? Swap to I2VA: keep the I2VA first line, describe Picture 1 as Shot 1 at 0.00s, then write the next action — do not re-describe a different product.

Copy-paste (8-second FL2VA, single shot)
Use this prompt

How the reference pictures align with the target video — Picture 1 (from Shot 1) aligns with the 0.00-second mark of the target video; Picture 2 (from Shot 1) aligns with the 8.00-second mark of the target video. integrated_multimodal_description: [Shot 1] Live-action, cinematic, a closed oatmeal-colored carton sits on a pale oak table in the framing established by Picture 1, lid sealed, one-color mark reading "AURA MUG" facing camera. The camera pushes in with small amplitude at slow speed as two hands enter from the lower edge, lift the lid along its scored fold, and set it aside. Tissue paper parts. A speckled ceramic mug rises into the exact placement, rotation, and table spacing established by Picture 2 at the end of the shot. overall_soundscape: Soft room tone under a wooden table, then the dry scrape of a carton lid and the rustle of tissue. The mug taps once against oak as it settles. non_diegetic_music: N/A

What changed
alignment line first; S.SS = 8.00; one shot; carton type stays in "AURA MUG"; camera is type + amplitude + speed; no score, because a product land often reads cleaner silent-score.

Start/end still job · hosted on MiniMax H3 Max · generated-style still for planning

First-and-last-frame style still hosted on MiniMax H3 Max

Copy the T2VA block as-is.

Watch once full-screen, then change only the field that failed — description, soundscape, or music.

How to run it on MiniMax H3 Max

The MiniMax H3 Max home is the overview. Paste into the video generator, not the home page.

  1. 1

    Choose the mode with the table above.

    If you still need a first or last frame, generate or crop it on the image generator first.

  2. 2

    Open the MiniMax H3 Max video generator.

    Keep MiniMax H3 Max selected.

  3. 3

    Set duration to a whole second from 5 to 15.

    If the prompt says 8.00, generate 8 seconds.

  4. 4

    Paste Prompt 1 (T2VA) or Prompt 2 (FL2VA).

    Attach stills only for I2VA / FL2VA / L2VA.

  5. 5

    Watch once without scrubbing, then scrub:

    Cut logic, identity, hands, on-screen type, whether sound matches events.

MiniMax H3 Ref2VA Prompt Guide: The Six Sections

This part of the MiniMax H3 prompting guide covers Ref2VA, MiniMax H3’s full-reference (reference-to-video) mode: instead of pinning one or two keyframes, the prompt says what each reference image, clip, or audio file is for. MiniMax’s h3-prompt-writing skill writes it as six sections in a fixed order, in English except for dialogue, lyrics, and visible text (full-reference guide, ref-en.txt).

subject_definitionsOne line per reference you will track: a person, a place, a prop, a voice, or a source clip, each with its label and the features to follow.<Subject 1> is the young woman in <Picture 1>, with long dark hair, a blue cardigan, and a thin silver necklace.
summaryOne short paragraph that starts with a task type in square brackets, then says what happens and what each reference is for. No new labels here.[reference generation + audio reference] The target video shows <Subject 1> serving coffee in <Subject 2>…
retention_analysisOne line per label: where it appears and how much of it is kept.<Subject 1> (appears in [Shot 1], [Shot 2]): fully_preserved - her face, hair, and cardigan are retained.
detailed_descriptionThe main body. A sentence or two on style before [Shot 1], then every shot in playback order, citing labels where they show up.The target video is in a warm documentary style. [Shot 1] A medium shot frames <Subject 1> behind the counter…
overall_soundscapeRoom tone, ambience, and physical sound across the whole clip, plus any copied or referenced audio layer.Low café room tone and the hiss of an espresso machine continue throughout.
non_diegetic_musicScore only the audience hears: instruments, tempo, how it builds. N/A when there is none.A slow solo acoustic guitar, quiet under the dialogue, with no swell.

Ref2VA Labels, Markers, and Task Types

Ref2VA uses four labels. <Subject N> is something visible you reuse: a person, an animal, a room, a prop, a style, or a move. One subject can come from several files, and one file can supply several subjects. Every image you add is a <Picture N>. It gets a line of its own only when it is an actual frame: a first frame, a last frame, a keyframe, or a storyboard for named shots. An image that only shows what a person or place looks like is cited inside that subject’s line, as in “<Subject 1> is the woman in <Picture 1>”. <Video N> is a source clip you edit, continue, or borrow cuts and camera rhythm from. <Audio N> is a sound file, or a clip’s audio track, that is copied or referenced. Number the labels in the order you add the files; images, clips, and audio each count from 1, and a label keeps the same meaning in all six sections.

In retention_analysis, visible references take one of four markers: fully_preserved, partially_preserved, attribute_transfer (a trait moves onto a different subject), or weak_reference (only the broad look carries over). Audio takes fully_copy, partially_copy, reference (timbre, rhythm, or style only), or weak_reference.

The summary’s task type follows what each file does. Use reference generation when references guide a character, scene, style, or camera move, and keyframe completion when an image is an actual frame. Video editing and video continuation apply only when you change or extend a source clip. Audio reuse means the sound itself is copied, while audio reference means only its voice, style, or beat is followed. Join several with " + ", for example [video editing + audio reuse].

Two rules from the guide are easy to miss. When a referenced person speaks, write both labels, <Subject 1> (S1), and keep the line inside <d>. When you borrow only a voice’s timbre, do not carry the reference audio’s words into the new clip. For a generation job, MiniMax suggests 350–500 English words of detailed_description.

MiniMax full-reference prompt guide, ref-en.txt (GitHub)

Copy-Ready Ref2VA Prompt Example: Two Images and a Voice Clip

Written from MiniMax’s official full-reference guide; we have not run this exact prompt on this site yet. The generator numbers files in the order you add them. MiniMax’s guide calls images <Picture N>, and this reference-to-video mode is also set up for plain names such as Image 1 and Audio 1, so if a take seems to ignore a reference, try those. Use photos and a voice of yourself or of someone who has agreed: our Acceptable Use Policy does not allow cloning a real person’s voice or likeness without consent.

Prompt 3 — Ref2VA (two images and a voice clip)

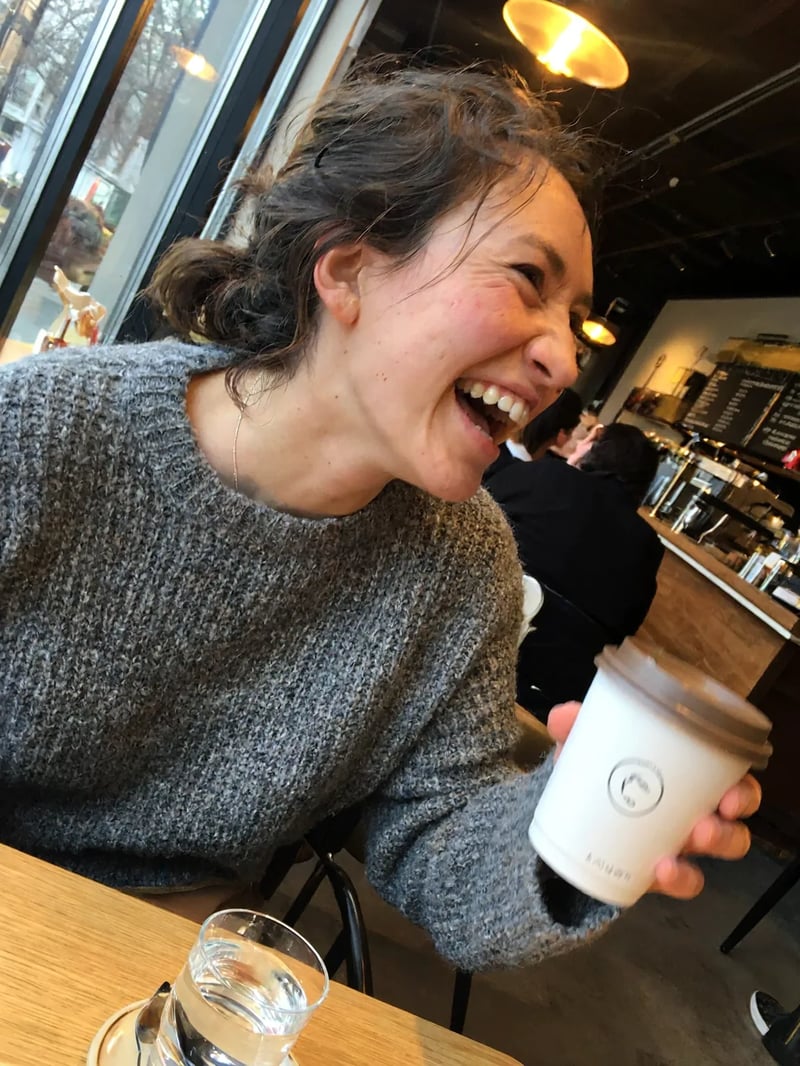
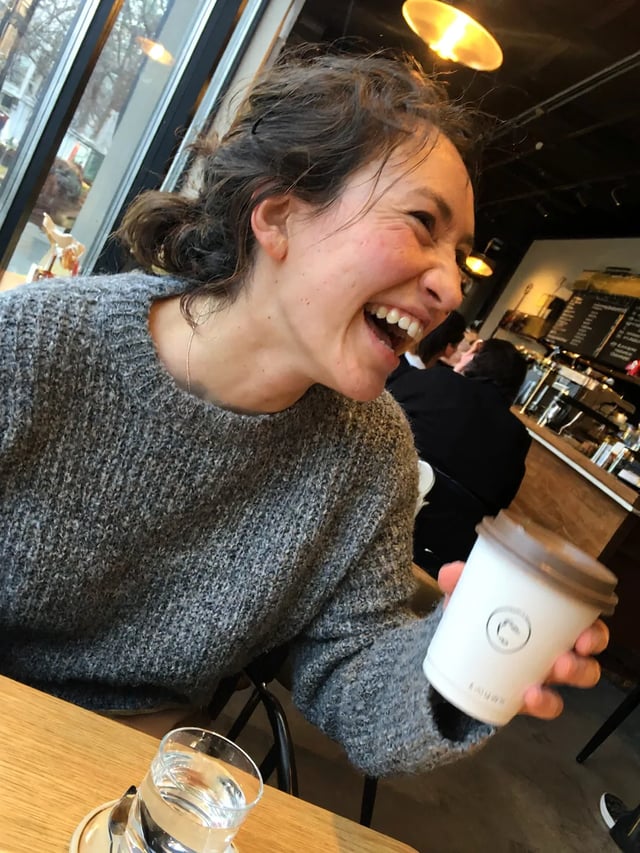
Add the files in this order: a photo of the person in a café (<Picture 1>, like the portrait here), a photo of the mug (<Picture 2>), then a few seconds of the same person talking (<Audio 1>). Set the length to 8 seconds so the cut at 00:04.500 lands inside the clip.

Keep the six headings and their order, and swap the person, product, and spoken line for your own. The copy button keeps the line breaks.

Ref2VA prompt (8 seconds)
Use this prompt

subject_definitions: <Subject 1> is the young woman in <Picture 1>, in her late twenties, with messy shoulder-length dark hair and a soft gray knit sweater. <Subject 2> is the busy café in <Picture 1>, with mixed daylight from the front window, warm bulbs hanging from the ceiling, and small wooden tables set close together. <Subject 3> is the speckled cream ceramic mug in <Picture 2>, with a rounded handle and a one-color mark reading "AURA MUG" on its side. <Audio 1> is the voice-timbre reference for <Subject 1> (S1), a bright, relaxed speaking voice. summary: [reference generation + audio reference] The target video shows <Subject 1> at a window table in <Subject 2> as a barista's hand sets <Subject 3> down in front of her. She lifts it, takes a sip, and speaks one line in the voice timbre referenced from <Audio 1>. A second shot closes in on <Subject 3> on the table. retention_analysis: <Subject 1> (appears in [Shot 1]): fully_preserved - her face, messy dark hair, and gray knit sweater are retained. <Subject 2> (appears in [Shot 1], [Shot 2]): fully_preserved - the window daylight, hanging ceiling bulbs, and close-set wooden tables are retained. <Subject 3> (appears in [Shot 1], [Shot 2]): fully_preserved - the speckled cream glaze, rounded handle, and "AURA MUG" mark are retained. <Audio 1>: reference - its vocal timbre guides the delivery of <Subject 1> without copying the original signal. detailed_description: The target video is in a warm, natural documentary style with mixed window daylight, warm ceiling bulbs, and a shallow depth of field. [Shot 1] A medium shot at eye level frames <Subject 1>, the young woman with messy shoulder-length dark hair and a soft gray knit sweater, sitting at a small wooden table by the front window of <Subject 2>. Other customers talk at the close-set tables behind her, softly out of focus under the warm hanging bulbs, and daylight from the window falls across the left side of her face. A small plate with half a croissant and a folded paper napkin sits near her elbow, and a phone lies face down beside it. A barista's hand enters from the right edge, sets down <Subject 3>, the speckled cream mug with its "AURA MUG" mark facing the camera, and withdraws. <Subject 1> wraps both hands around the mug, lifts it, and takes a small sip while the camera pushes in with small amplitude at slow speed. She lowers the mug a little, glances at the mark on its side, and smiles. Then, looking just past the lens and using the bright, relaxed voice timbre referenced from <Audio 1>, <Subject 1> (S1) says, <d>[English] Okay, this is my new favorite mug.</d> She laughs softly, tucks a loose strand of hair behind her ear, and keeps holding the mug close to her chin. [Shot 2] At 00:04.500, the shot cuts to a close-up of <Subject 3> set back down on the wooden table of <Subject 2>. Thin steam rises from the coffee, the "AURA MUG" mark stays sharp and readable, and the bright window and warm bulbs blur into soft shapes behind it, while a passer-by crosses the street outside as a blurred silhouette. The hand of <Subject 1> rests on the rounded handle, turns the mug a quarter turn so the mark ends square to the camera, then slides out of frame to the left. The window light catches the brown speckles in the cream glaze while the camera holds still and a last curl of steam drifts out of the top of the frame. overall_soundscape: Busy café room tone with low overlapping chatter, the clink of cups on saucers, a distant espresso-machine hiss, and the soft knock of ceramic on wood continue throughout. non_diegetic_music: N/A

Labels
Picture 1 supplies two subjects, the woman and the café, and Picture 2 supplies the mug; the recording keeps its own <Audio 1> line. Pictures that only show what something looks like are cited inside those lines instead of getting lines of their own.
Task type
[reference generation + audio reference]: the pictures guide who, where, and what, and the voice clip is followed for timbre only, not copied into the soundtrack.
Speaker
<Subject 1> (S1) says who she is and who is talking at the same time; the spoken line sits inside <d> with its language tag.
Timing
[Shot 1] has no clock. [Shot 2] starts at 00:04.500, inside the 8-second clip.
Sound
overall_soundscape keeps the room and the physical sounds; non_diegetic_music is N/A so nothing competes with the line.
Check in the first take
Her face and sweater match Picture 1, "AURA MUG" stays readable after the quarter turn, the voice sounds like the recording but says only the new line, and the cut lands near 4.5 seconds.

Picture 1 here is a picture made with MiniMax H3 Image · the mug photo and the voice clip are yours to supply
Picture 1 in this example: a woman in a gray knit sweater laughing in a busy café, made with MiniMax H3 Image

Have the files ready?

Open reference to video, add the images, clips, and audio in the order your labels use, set the length, and paste the six sections.

What We Know vs What We Don't

Four text/keyframe shapes: T2VA, I2VA, FL2VA, L2VA, with fixed alignment lines and three fields in a fixed order (Hugging Face guide; GitHub base-en.txt, commit 35491cd, 2026-08-05)That every control in the video generator is labeled with those four acronyms. Paste the matching shape; attach stills when you have them.
MiniMax H3 Max follows the public launch specs: unified text/image/video/audio context, up to 15s, up to 2K, native stereo (launch post, 2026-07-31; open source, 2026-08-03; release notes)End-to-end generation time. There is no public, verifiable latency number to quote.
Hosted duration is 4–15 seconds, integer seconds; hosted resolution 768P / 2K; first/last-frame takes 0–2 images (platform video guide, accessed 2026-08-26)That a freeform sentence is auto-rewritten into the three fields on every run. Write the fields yourself.
Camera language is type + amplitude + speed inside the shot sentence; speakers use stable (S1) IDs; <d> keeps original wording (guide §4)Pixel-perfect carton marks or lip sync without a human pass. Zoom-check type and mouths before you ship.
Full-reference (Ref2VA) is a different six-section rewrite (GitHub README; prompt-writing skill)How the six sections behave on this site’s generator. The Ref2VA example is written from the official guide and has not been run here yet.

FAQ

Mode picked and fields filled?

Paste the block, attach stills if you have them, and keep the take that lands.